


Python数据正态性检验实现过程

本文详细介绍在Python中使用scipy库进行数据正态性检验的多种方法。涵盖Shapiro-Wilk检验(适用于小样本)、K-S检验、normaltest、Anderson-Darling检验以及偏度和峰度检验。通过具体函数定义、参数说明及代码示例,帮助开发者掌握如何判断数据是否符合正态分布,为T检验等统计分析奠定基础。
Python数据正态性检验概述
在进行数据分析或统计建模时,验证数据是否服从正态分布是常见且关键的步骤,因为许多统计假设(如T检验)均建立在数据符合正态分布的前提之上。
在Python环境中,实现正态性检验主要依赖scipy.stats模块,以下是几种常用的检验方法及其具体实现。
Shapiro-Wilk检验
1. scipy.stats.shapiro:Shapiro-Wilk检验。这是一个专门用于正态性检验的统计模块,其原假设为样本数据服从正态分布。
注意:该方法主要适用于小样本数据。
其函数调用形式如下:
def shapiro(x):
  """
  Perform the Shapiro-Wilk test for normality.

  The Shapiro-Wilk test tests the null hypothesis that the
  data was drawn from a normal distribution.

  Parameters
  ----------
  x : array_like
    Array of sample data.

  Returns
  -------
  W : float
    The test statistic.
  p-value : float
    The p-value for the hypothesis test.
其中x参数代表样本值序列。函数返回两个值,第一个为检验统计量,第二个为P值。当P值大于设定的显著性水平时,接受原假设,即认为数据符合正态分布。
K-S检验(Kolmogorov-Smirnov Test)
2. scipy.stats.kstest(K-S检验):该检验可用于多种分布的拟合优度测试,不仅限于正态分布。其原假设为数据符合指定的分布(如正态分布)。
其函数定义如下:
def kstest(rvs, cdf, args=(), N=20, alternative='two-sided', mode='approx'):
  """
  Perform the Kolmogorov-Smirnov test for goodness of fit.

  This performs a test of the distribution G(x) of an observed
  random variable against a given distribution F(x). Under the null
  hypothesis the two distributions are identical, G(x)=F(x). The
  alternative hypothesis can be either 'two-sided' (default), 'less'
  or 'greater'. The KS test is only valid for continuous distributions.

  Parameters
  ----------
  rvs : str, array or callable
    If a string, it should be the name of a distribution in `scipy.stats`.
    If an array, it should be a 1-D array of observations of random
    variables.
    If a callable, it should be a function to generate random variables;
    it is required to have a keyword argument `size`.
  cdf : str or callable
    If a string, it should be the name of a distribution in `scipy.stats`.
    If `rvs` is a string then `cdf` can be False or the same as `rvs`.
    If a callable, that callable is used to calculate the cdf.
  args : tuple, sequence, optional
    Distribution parameters, used if `rvs` or `cdf` are strings.
  N : int, optional
    Sample size if `rvs` is string or callable. Default is 20.
  alternative : {'two-sided', 'less','greater'}, optional
    Defines the alternative hypothesis (see explanation above).
    Default is 'two-sided'.
  mode : 'approx' (default) or 'asymp', optional
    Defines the distribution used for calculating the p-value.

     - 'approx' : use approximation to exact distribution of test statistic
     - 'asymp' : use asymptotic distribution of test statistic

  Returns
  -------
  statistic : float
    KS test statistic, either D, D+ or D-.
  pvalue : float
    One-tailed or two-tailed p-value.
主要参数说明如下:
rvs:待检验的数据序列。
cdf:指定要检验的分布类型,例如'norm'(正态分布)、'expon'(指数分布)、'rayleigh'(瑞利分布)、'gamma'(伽马分布)等。若设置为'norm',则检验正态分布。
alternative:默认为双侧检验,可设置为'less'或'greater'以进行单侧检验。
model:默认为'approx',表示使用检验统计量精确分布的近似值;设置为'asymp'时,则使用检验统计量的渐近分布。
函数返回值中,第一个值为统计量,第二个值为P值。
normaltest正态性检验
3. scipy.stats.normaltest:正态性检验,其原假设为样本来自正态分布。
其函数定义如下:
def normaltest(a, axis=0, nan_policy='propagate'):
  """
  Test whether a sample differs from a normal distribution.

  This function tests the null hypothesis that a sample comes
  from a normal distribution. It is based on D'Agostino and
  Pearson's [1]_, [2]_ test that combines skew and kurtosis to
  produce an omnibus test of normality.


  Parameters
  ----------
  a : array_like
    The array containing the sample to be tested.
  axis : int or None, optional
    Axis along which to compute test. Default is 0. If None,
    compute over the whole array `a`.
  nan_policy : {'propagate', 'raise', 'omit'}, optional
    Defines how to handle when input contains nan. 'propagate' returns nan,
    'raise' throws an error, 'omit' performs the calculations ignoring nan
    values. Default is 'propagate'.

  Returns
  -------
  statistic : float or array
    ``s^2 + k^2``, where ``s`` is the z-score returned by `skewtest` and
    ``k`` is the z-score returned by `kurtosistest`.
  pvalue : float or array
    A 2-sided chi squared probability for the hypothesis test.
主要参数说明如下:
axis=None表示对整个数据数组进行检验,默认值为0。
nan_policy:处理输入数据中包含NaN值的方式。'propagate'返回空值;'raise'抛出错误;'omit'则忽略NaN值进行计算。
函数返回值中,第一个值为统计量,第二个值为P值。
Anderson-Darling检验
4. scipy.stats.anderson:由scipy.stats.kstest改进而来,用于检验样本是否属于特定分布(如正态分布、指数分布、logistic分布或Gumbel分布等)。
其函数定义如下:
def anderson(x, dist='norm'):
  """
  Anderson-Darling test for data coming from a particular distribution

  The Anderson-Darling tests the null hypothesis that a sample is
  drawn from a population that follows a particular distribution.
  For the Anderson-Darling test, the critical values depend on
  which distribution is being tested against. This function works
  for normal, exponential, logistic, or Gumbel (Extreme Value
  Type I) distributions.

  Parameters
  ----------
  x : array_like
    array of sample data
  dist : {'norm','expon','logistic','gumbel','gumbel_l', gumbel_r',
    'extreme1'}, optional
    the type of distribution to test against. The default is 'norm'
    and 'extreme1', 'gumbel_l' and 'gumbel' are synonyms.

  Returns
  -------
  statistic : float
    The Anderson-Darling test statistic
  critical_values : list
    The critical values for this distribution
  significance_level : list
    The significance levels for the corresponding critical values
    in percents. The function returns critical values for a
    differing set of significance levels depending on the
    distribution that is being tested against.
主要参数说明如下:
x表示样本数据,dist表示要检验的分布类型。
函数返回三个值:第一个为统计值,第二个为临界值(评价值),第三个为显著性水平列表;临界值与显著性水平一一对应。
不同分布对应的显著性水平不同。
Critical values provided are for the following significance levels:

  normal/exponenential
    15%, 10%, 5%, 2.5%, 1%
  logistic
    25%, 10%, 5%, 2.5%, 1%, 0.5%
  Gumbel
    25%, 10%, 5%, 2.5%, 1%
统计值与临界值的对比规则:当统计值大于这些临界值时,在对应的显著性水平下拒绝原假设,即认为数据不属于该指定分布。
If the returned statistic is larger than these critical values then for the corresponding significance level, the null hypothesis that the data come from the chosen distribution can be rejected.
偏度与峰度检验
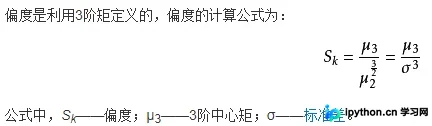
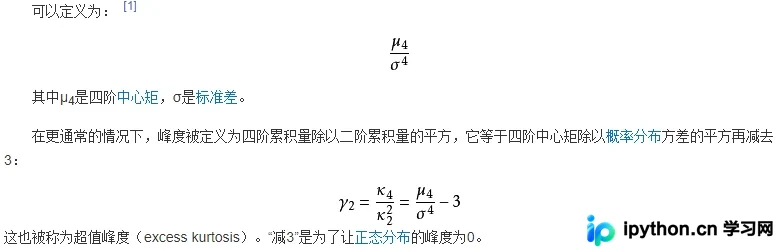
5. skewtest和kurtosistest检验:用于检验样本的偏度(skewness)和峰度(kurtosis)是否与正态分布一致。正态分布的理论偏度为0,峰度为3。
偏度:定义为样本的标准三阶中心矩。
峰度:定义为样本的标准四阶中心矩。
代码实现示例
6. 完整代码示例如下:
import numpy as np
from scipy import stats

a = np.random.normal(0,2,50)
b = np.linspace(0, 10, 100)

# Shapiro-Wilk test
S,p = stats.shapiro(a)
print('the shapiro test result is:',S,',',p)

# kstest(K-S检验)
K,p = stats.kstest(a, 'norm')
print(K,p)

# normaltest
N,p = stats.normaltest(b)
print(N,p)

# Anderson-Darling test
A,C,p = stats.anderson(b,dist='norm')
print(A,C,p)
以上就是本文的全部内容,希望对大家的学习有所帮助,也希望大家多多支持本站。
本站声明
本文内容仅供参考,不代表本站观点。转载或引用请注明出处。如发现内容问题,请通过联系我们页面反馈。















