


Python实现高效遗传算法:从原理到代码详解

本文详细介绍如何使用Python实现高效的遗传算法。内容涵盖算法核心概念如适应度计算、二进制编码策略、交叉变异操作及种群淘汰机制。通过具体代码示例,展示如何初始化种群、计算染色体长度并迭代优化,适用于函数优化及模型训练场景。
遗传算法概述
遗传算法是一种基于自然选择与遗传机制的启发式优化算法。
当面临待优化函数求解问题时,该算法提供了有效的解决思路。假设存在变量x,通过特定函数可计算对应输出y。若通过预设x得到预测值y_pred,则y_pred与目标y之间的差距越小越好。为此,需引入适应度(fitness)概念来量化个体优劣。
通常定义适应度公式为 fitness = 1/(1+|y_pred - y|),其中误差越小,适应度值越大,意味着该个体在进化过程中越容易存活并被保留。
算法核心步骤
算法的整体设计思路主要包含以下几个关键步骤:
种群初始化与编码
第一步是初始化种群。在指定区间(例如[-100, 100])内随机生成一组初始个体[x1, x2, x3...]。这些个体初始为十进制形式,为了便于后续的交叉与变异操作,需将其转化为二进制编码。此时面临的关键问题是确定二进制编码的位数,即编码长度(code length)。
编码长度的确定涉及信号处理相关知识。例如,两位二进制数最大值为3(即11),可将区间划分为4个子区间,每个子区间的长度为range/4。为确保精度,需使每个子区间的长度小于预设精度,即 range/n < 精度,其中n为二进制能表示的最大整数。通过该关系可反解出所需的二进制位数。
编码与解码机制
第二步是编写编码与解码函数。编码函数(code)负责将十进制变量x1, x2...转换为二进制串;解码函数(decode)则在交叉和变异操作后,将二进制串重新转换回十进制数,以便计算适应度。
交叉与变异操作
第三步是实现交叉与变异操作。交叉操作相对简单,随机选取一个交叉点(point),将两个父代个体在该点后的部分进行交换。变异操作同样随机选取一个位点,将该位的值由0变为1或由1变为0,以维持种群多样性。
适应度评估与淘汰
第四步是对经过交叉变异产生的新个体计算适应度,并执行种群淘汰策略。保留适应度最高的部分个体,作为下一代的候选种群。
第五步是将当前最优个体保留并继续执行上述迭代过程,直到达到预设的最大迭代次数(iteration)为止。
Python代码实现
以下是具体的Python代码实现:
import numpy as np
import pandas as pd
import random
from scipy.optimize import fsolve
import matplotlib.pyplot as plt
import heapq
from sklearn.model_selection import train_test_split
from tkinter import _flatten
from sklearn.utils import shuffle
from sklearn import preprocessing
from sklearn.decomposition import PCA
from matplotlib import rcParams


# 求染色体长度
def getEncodeLength(decisionvariables, delta):
 # 将每个变量的编码长度放入数组
 lengths = []
 for decisionvar in decisionvariables:
  uper = decisionvar[1]
  low = decisionvar[0]
  # res()返回一个数组
  res = fsolve(lambda x: ((uper - low) / delta - 2 ** x + 1), 30)
  # ceil()向上取整
  length = int(np.ceil(res[0]))
  lengths.append(length)
 # print("染色体长度:", lengths)
 return lengths


# 随机生成初始化种群
def getinitialPopulation(length, populationSize):
 chromsomes = np.zeros((populationSize, length), dtype=np.int)
 for popusize in range(populationSize):
  # np.random.randit()产生[0,2)之间的随机整数,第三个参数表示随机数的数量
  chromsomes[popusize, :] = np.random.randint(0, 2, length)
 return chromsomes


# 染色体解码得到表现形的解
def getDecode(population, encodelength, decisionvariables, delta):
 # 得到population中有几个元素
 populationsize = population.shape[0]
 length = len(encodelength)
 decodeVariables = np.zeros((populationsize, length), dtype=np.float)
 # 将染色体拆分添加到解码数组decodeVariables中
 for i, populationchild in enumerate(population):
  # 设置起始点
  start = 0
  for j, lengthchild in enumerate(encodelength):
   power = lengthchild - 1
   decimal = 0
   start_end = start + lengthchild
   for k in range(start, start_end):
    # 二进制转为十进制
    decimal += populationchild[k] * (2 ** power)
    power = power - 1
   # 从下一个染色体开始
   start = start_end
   lower = decisionvariables[j][0]
   uper = decisionvariables[j][1]
   # 转换为表现形
   decodevalue = lower + decimal * (uper - lower) / (2 ** lengthchild - 1)
   # 将解添加到数组中
   decodeVariables[i][j] = decodevalue

 return decodeVariables


# 选择新的种群
def selectNewPopulation(decodepopu, cum_probability):
 # 获取种群的规模和
 m, n = decodepopu.shape
 # 初始化新种群
 newPopulation = np.zeros((m, n))
 for i in range(m):
  # 产生一个0到1之间的随机数
  randomnum = np.random.random()
  # 轮盘赌选择
  for j in range(m):
   if (randomnum < cum_probability[j]):
    newPopulation[i] = decodepopu[j]
    break
 return newPopulation


# 新种群交叉
def crossNewPopulation(newpopu, prob):
 m, n = newpopu.shape
 # uint8将数值转换为无符号整型
 numbers = np.uint8(m * prob)
 # 如果选择的交叉数量为奇数,则数量加1
 if numbers % 2 != 0:
  numbers = numbers + 1
 # 初始化新的交叉种群
 updatepopulation = np.zeros((m, n), dtype=np.uint8)
 # 随机生成需要交叉的染色体的索引号
 index = random.sample(range(m), numbers)
 # 不需要交叉的染色体直接复制到新的种群中
 for i in range(m):
  if not index.__contains__(i):
   updatepopulation[i] = newpopu[i]
 # 交叉操作
 j = 0
 while j < numbers:
  # 随机生成一个交叉点,np.random.randint()返回的是一个列表
  crosspoint = np.random.randint(0, n, 1)
  crossPoint = crosspoint[0]
  # a = index[j]
  # b = index[j+1]
  updatepopulation[index[j]][0:crossPoint] = newpopu[index[j]][0:crossPoint]
  updatepopulation[index[j]][crossPoint:] = newpopu[index[j + 1]][crossPoint:]
  updatepopulation[index[j + 1]][0:crossPoint] = newpopu[j + 1][0:crossPoint]
  updatepopulation[index[j + 1]][crossPoint:] = newpopu[index[j]][crossPoint:]
  j = j + 2
 return updatepopulation


# 变异操作
def mutation(crosspopulation, mutaprob):
 # 初始化变异种群
 mutationpopu = np.copy(crosspopulation)
 m, n = crosspopulation.shape
 # 计算需要变异的基因数量
 mutationnums = np.uint8(m * n * mutaprob)
 # 随机生成变异基因的位置
 mutationindex = random.sample(range(m * n), mutationnums)
 # 变异操作
 for geneindex in mutationindex:
  # np.floor()向下取整返回的是float型
  row = np.uint8(np.floor(geneindex / n))
  colume = geneindex % n
  if mutationpopu[row][colume] == 0:
   mutationpopu[row][colume] = 1
  else:
   mutationpopu[row][colume] = 0
 return mutationpopu


# 找到重新生成的种群中适应度值最大的染色体生成新种群
def findMaxPopulation(population, maxevaluation, maxSize):
 #将数组转换为列表
 #maxevalue = maxevaluation.flatten()
 maxevaluelist = maxevaluation
 # 找到前100个适应度最大的染色体的索引
 maxIndex = map(maxevaluelist.index, heapq.nlargest(maxSize, maxevaluelist))
 index = list(maxIndex)
 colume = population.shape[1]
 # 根据索引生成新的种群
 maxPopulation = np.zeros((maxSize, colume))
 i = 0
 for ind in index:
  maxPopulation[i] = population[ind]
  i = i + 1
 return maxPopulation


# 得到每个个体的适应度值及累计概率
def getFitnessValue(decode,x_train,y_train):
 # 得到种群的规模和决策变量的个数
 popusize, decisionvar = decode.shape

 fitnessValue = []
 for j in range(len(decode)):
  W1 = decode[j][0:20].reshape(4,5)
  V1 = decode[j][20:25].T
  W2 = decode[j][25:45].reshape(5,4)
  V2 = decode[j][45:].T
  error_all = []
  for i in range(len(x_train)):
   #get values of hidde layer
   X2 = sigmoid(x_train[i].T.dot(W1)+V1)
   #get values of prediction y
   Y_hat = sigmoid(X2.T.dot(W2)+V2)
   #get error when input dimension is i
   error = sum(abs(Y_hat - y_train[i]))
   error_all.append(error)

  #get fitness when W and V is j
  fitnessValue.append(1/(1+sum(error_all)))

 # 得到每个个体被选择的概率
 probability = fitnessValue / np.sum(fitnessValue)
 # 得到每个染色体被选中的累积概率,用于轮盘赌算子使用
 cum_probability = np.cumsum(probability)
 return fitnessValue, cum_probability


def getFitnessValue_accuracy(decode,x_train,y_train):
 # 得到种群的规模和决策变量的个数
 popusize, decisionvar = decode.shape

 fitnessValue = []
 for j in range(len(decode)):
  W1 = decode[j][0:20].reshape(4,5)
  V1 = decode[j][20:25].T
  W2 = decode[j][25:45].reshape(5,4)
  V2 = decode[j][45:].T
  accuracy = []
  for i in range(len(x_train)):
   #get values of hidde layer
   X2 = sigmoid(x_train[i].T.dot(W1)+V1)
   #get values of prediction y
   Y_hat = sigmoid(X2.T.dot(W2)+V2)
   #get error when input dimension is i
   accuracy.append(sum(abs(np.round(Y_hat) - y_train[i])))
  fitnessValue.append(sum([m == 0 for m in accuracy])/len(accuracy))
 # 得到每个个体被选择的概率
 probability = fitnessValue / np.sum(fitnessValue)
 # 得到每个染色体被选中的累积概率,用于轮盘赌算子使用
 cum_probability = np.cumsum(probability)
 return fitnessValue, cum_probability


def getXY():
 # 要打开的文件名
 data_set = pd.read_csv('all-bp.csv', header=None)
 # 取出“特征”和“标签”,并做了转置,将列转置为行
 X_minMax1 = data_set.iloc[:, 0:12].values
 # 前12列是特征
 min_max_scaler = preprocessing.MinMaxScaler()
 X_minMax = min_max_scaler.fit_transform(X_minMax1) # 0-1 range
 transfer = PCA(n_components=0.9)
 data1 = transfer.fit_transform(X_minMax)
 #print('PCA processed shape:',data1.shape)
 X = data1
 Y = data_set.iloc[ : , 12:16].values # 后3列是标签

 # 分训练和测试集
 x_train, x_test, y_train, y_test = train_test_split(X, Y, test_size=0.3)
 return x_train, x_test, y_train, y_test


def sigmoid(z):
 return 1 / (1 + np.exp(-z))
需要注意的是,适应度函数的具体形式需根据实际应用场景进行调整。
optimalvalue = []
optimalvariables = []

# 两个决策变量的上下界,多维数组之间必须加逗号
decisionVariables = [[-100,100]]*49
# 精度
delta = 0.001
# 获取染色体长度
EncodeLength = getEncodeLength(decisionVariables, delta)
# 种群数量
initialPopuSize = 100
# 初始生成100个种群,20,5,20,4分别对用W1,V1,W2,V2
population = getinitialPopulation(sum(EncodeLength), initialPopuSize)
print("polpupation.shape:",population.shape)
# 最大进化代数
maxgeneration = 4000
# 交叉概率
prob = 0.8
# 变异概率
mutationprob = 0.5
# 新生成的种群数量
maxPopuSize = 30
x_train, x_test, y_train, y_test = getXY()


for generation in range(maxgeneration):
 # 对种群解码得到表现形
 print(generation)
 decode = getDecode(population, EncodeLength, decisionVariables, delta)
 #print('the shape of decode:',decode.shape

 # 得到适应度值和累计概率值
 evaluation, cum_proba = getFitnessValue_accuracy(decode,x_train,y_train)
 # 选择新的种群
 newpopulations = selectNewPopulation(population, cum_proba)
 # 新种群交叉
 crossPopulations = crossNewPopulation(newpopulations, prob)
 # 变异操作
 mutationpopulation = mutation(crossPopulations, mutationprob)

 # 将父母和子女合并为新的种群
 totalpopulation = np.vstack((population, mutationpopulation))
 # 最终解码
 final_decode = getDecode(totalpopulation, EncodeLength, decisionVariables, delta)
 # 适应度评估
 final_evaluation, final_cumprob = getFitnessValue_accuracy(final_decode,x_train,y_train)
 #选出适应度最大的100个重新生成种群
 population = findMaxPopulation(totalpopulation, final_evaluation, maxPopuSize)

 # 找到本轮中适应度最大的值
 optimalvalue.append(np.max(final_evaluation))
 index = np.where(final_evaluation == max(final_evaluation))
 optimalvariables.append(list(final_decode[index[0][0]]))
fig = plt.figure(dpi = 160,figsize=(5,4))
config = {
"font.family":"serif", #serif
"font.size": 10,
"mathtext.fontset":'stix',
}
rcParams.update(config)
plt.plot(np.arange(len(optimalvalue)), optimalvalue, color="y", lw=0.8, ls='-', marker='o', ms=8)
# 图例设置
plt.xlabel('Iteration')
plt.ylabel('Accuracy')
plt.show()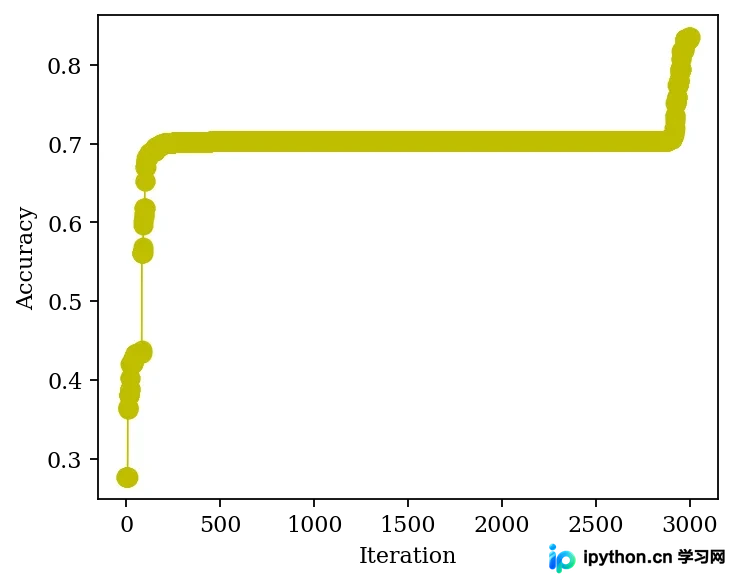
以上即为Python实现高效遗传算法的完整流程与代码解析,更多关于Python遗传算法的深入资料,建议参考本站其他相关文章。
本站声明
本文内容仅供参考,不代表本站观点。转载或引用请注明出处。如发现内容问题,请通过联系我们页面反馈。















