


Python实现卡方Chi特征检验提取关键文本特征

本文介绍如何利用Python实现卡方(Chi)特征检验以提取关键文本特征。通过计算单词与类别间的依赖关系,筛选出最具区分度的词汇。文章提供了完整的代码示例,包括基础实现与简化算法,并分析了二分类场景下的公式推导及实际运行结果,帮助开发者理解特征选择的原理与应用。
理论
| 类别classi | 非类别classi | |
| 包含单词wordj的文档数 | A | B |
| 不包含单词wordj的文档数 | C | D |
卡方特征提取的核心在于衡量类别classi与单词wordj之间的依赖程度,其基础计算公式如下
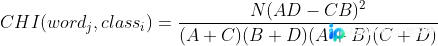
公式中,N代表文档的总数量;A表示既包含单词wordj又属于classi类别的文档数量;B表示包含单词wordj但不属于classi类别的文档数量;C表示不包含单词wordj但属于classi类别的文档数量;D表示既不包含单词wordj也不属于classi类别的文档数量。需要特别注意的是
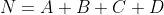
单词wordj最终的CHI值由以下公式计算得出,其中P(classi)指代属于classi类别的文档在所有文档中出现的概率,k为类别的总数
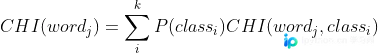
代码
以下以二分类任务为例展示Python实现:该函数的第一个参数是文档列表,其中每个文档由多个单词通过空格连接组成;第二个参数是对应的标签列表,标识每个文档的类别;第三个参数用于指定保留前百分之多少的高频单词。
# documents = [document_1, document_2, document_3, ...]
# document_i = "word_1 word_2 word_3"
# labels is a list combined with 0 and 1
def feature_word_select(documents:list, labels:list, percentage:float):

    # get all words
    word_set = set()
    for document in documents:
        words = document.split()
        word_set.update(words)
    word_list = list(word_set)
    word_list.sort()

    sorted_words = chi(word_list, documents, labels)
    top_k_words = sorted_words[:int(percentage * len(sorted_words))]

    return top_k_words
代码首先初始化一个集合word_set,随后遍历所有文档,利用split()函数将每个文档切分为单词列表,并将这些单词添加到集合中。得益于集合的去重特性,word_set会自动过滤重复单词。收集完成后,将集合转换为列表word_list。
将单词列表、文档列表和标签列表传入chi函数,该函数会返回按卡方值降序排列的单词列表sorted_words。
最后,根据设定的百分比percentage,选取排名靠前的单词作为最终的特征单词集合。
函数cal_chi_word_class()用于计算特定单词在类别0和类别1下的CHI值,即CHI(word, 0)和CHI(word, 1)。此处A1代表属于类别1的A值,A0代表属于类别0的A值。
在二分类场景中,A1的值实际上等同于B0,C1的值等同于D0。因此,只需计算A1、B1、C1和D1,即可推导出A0、B0、C0和D0。
此外,由于文档总数N在计算CHI(word, 0)和CHI(word, 1)时作为公共分子保持不变,因此可以省略其参与计算;同时,因为A1+C1等于B0+D0,且B1+D1等于A0+C0,所以CHI(word, 0)和CHI(word, 1)的分母部分可以进行简化处理。
# calculate chi(word,1) and chi(word,0)
def cal_chi_word_class(word, labels, documents):
    N = len(documents)
    A1, B1, C1, D1 = 0., 0., 0., 0.
    A0, B0, C0, D0 = 0., 0., 0., 0.
    for i in range(len(documents)):
        if word in documents[i].split():
            if labels[i] == 1:
                A1 += 1
                B0 += 1
            else:
                B1 += 1
                A0 += 1
        else:
            if labels[i] == 1:
                C1 += 1
                D0 += 1
            else:
                D1 += 1
                C0 += 1
    chi_word_1 = N * (A1*D1-C1*B1)**2 / ((A1+C1)*(B1+D1)*(A1+B1)*(C1+D1))
    chi_word_0 = N * (A0*D0-C0*B0)**2 / ((A0+C0)*(B0+D0)*(A0+B0)*(C0+D0))
    return chi_word_1, chi_word_0
简化后的公式如下
# calculate chi(word,1) and chi(word,0)
def cal_chi_word_class(word, labels, documents):
    A1, B1, C1, D1 = 0., 0., 0., 0.
    for i in range(len(documents)):
        if word in documents[i].split():
            if labels[i] == 1:
                A1 += 1
            else:
                B1 += 1
        else:
            if labels[i] == 1:
                C1 += 1
            else:
                D1 += 1
    A0, B0, C0, D0 = B1, A1, D1, C1
    chi_word_1 = (A1*D1-C1*B1)**2 / ((A1+B1)*(C1+D1))
    chi_word_0 = (A0*D0-C0*B0)**2 / ((A0+B0)*(C0+D0))
    return chi_word_1, chi_word_0
在chi函数中调用cal_chi_word_class函数,即可计算出每个单词的卡方值,并以字典形式存储。最后对字典中的所有值进行排序,提取出排序后的单词列表。
def chi(word_list, documents, labels):
    P1 = labels.count(1) / len(documents)
    P0 = 1 - P1
    dic = {}
    for word in word_list:
        chi_word_1, chi_word_0 = cal_chi_word_class(word, labels, documents)
        chi_word = P0 * chi_word_0 + P1 * chi_word_1
        dic[word] = chi_word
    sorted_list = sorted(dic.items(), key=lambda x:x[1], reverse=True)
    sorted_chi_word = [x[0] for x in sorted_list]
    return sorted_chi_word
测试代码示例。此处省略了数据预处理步骤,documents列表中的每个元素document_i均由若干单词或符号通过空格拼接而成。
def main():
    documents = ["today i am happy !", "she is not happy at all", "let us go shopping !",
        "mike was so sad last night", "amy did not love it", "it is so amazing !"
    ]
    labels = [1, 0, 1, 0, 0, 1]
    words = feature_word_select(documents, labels, 0.3)
    print(words)

if __name__ == '__main__':
    main()
运行结果如下所示
['!', 'not', 'all', 'am', 'amazing', 'amy', 'at']
进一步地,可以在chi函数中输出sorted_list(即每个单词对应的卡方值),结果如下。需要注意的是,此处输出的是经过简化处理的数值,并非真实的原始卡方值。如需获取原始值,请使用完整的cal_chi_word_class()函数。
[('!', 9.0), ('not', 4.5), ('all', 1.8), ('am', 1.8), ('amazing', 1.8), ('amy', 1.8), ('at', 1.8), ('did', 1.8), ('go', 1.8), ('i', 1.8), ('last', 1.8), ('let', 1.8), ('love', 1.8), ('mike', 1.8), ...]
完整代码
# calculate chi(word,1) and chi(word,0)
def cal_chi_word_class(word, labels, documents):
    A1, B1, C1, D1 = 0., 0., 0., 0.
    for i in range(len(documents)):
        if word in documents[i].split():
            if labels[i] == 1:
                A1 += 1
            else:
                B1 += 1
        else:
            if labels[i] == 1:
                C1 += 1
            else:
                D1 += 1
    A0, B0, C0, D0 = B1, A1, D1, C1
    chi_word_1 = (A1*D1-C1*B1)**2 / ((A1+B1)*(C1+D1))
    chi_word_0 = (A0*D0-C0*B0)**2 / ((A0+B0)*(C0+D0))
    return chi_word_1, chi_word_0

def chi(word_list, documents, labels):
    P1 = labels.count(1) / len(documents)
    P0 = 1 - P1
    dic = {}
    for word in word_list:
        chi_word_1, chi_word_0 = cal_chi_word_class(word, labels, documents)
        chi_word = P0 * chi_word_0 + P1 * chi_word_1
        dic[word] = chi_word
    sorted_list = sorted(dic.items(), key=lambda x:x[1], reverse=True)
    sorted_chi_word = [x[0] for x in sorted_list]
    return sorted_chi_word

# documents = [document_1, document_2, document_3, ...]
# document_i = "word_1 word_2 word_3"
# labels is a list combined with 0 and 1
def feature_word_select(documents:list, labels:list, percentage:float):
    # get all words
    word_set = set()
    for document in documents:
        words = document.split()
        word_set.update(words)
    word_list = list(word_set)
    word_list.sort()

    sorted_words = chi(word_list, documents, labels)
    top_k_words = sorted_words[:int(percentage * len(sorted_words))]

    return top_k_words

def main():
    documents = ["today i am happy !", "she is not happy at all", "let us go shopping !",
        "mike was so sad last night", "amy did not love it", "it is so amazing !"
    ]
    labels = [1, 0, 1, 0, 0, 1]
    words = feature_word_select(documents, labels, 0.3)
    print(words)

if __name__ == '__main__':
    main()
题外话
卡方特征选择仅关注单词是否在文档中出现,而未考虑单词出现的频率或次数,因此筛选出的特征单词可能存在一定的不准确性。
到此这篇关于Python利用卡方Chi特征检验实现提取关键文本特征的文章就介绍到这了,更多相关Python提取关键文本特征内容请搜索本站以前的文章或继续浏览下面的相关文章希望大家以后多多支持本站!
本站声明
本文内容仅供参考,不代表本站观点。转载或引用请注明出处。如发现内容问题,请通过联系我们页面反馈。















