


Python heapq模块源码深度解析:从原理到实现

本文深入解析Python heapq模块,涵盖heappush、heapify及heappop等核心函数的使用与源码实现。通过对比下沉(siftup)与上浮(siftdown)算法,揭示其优化策略,帮助开发者理解堆结构在优先队列中的应用及性能优化细节。
引言
作为一个极具实用价值的内置模块,heapq 却常被许多开发者忽视——笔者也是近期偶然发现其存在,不禁感叹。尽管知晓者不多,但这并不影响它的高效与易用性。
heapq 模块基于 Python 列表实现了最小堆排序算法。
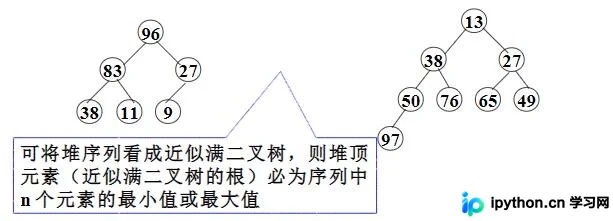
堆是一种树形数据结构,其中子节点与父节点遵循特定的排序关系。由于堆排序通常基于满二叉树构建,因此可以使用列表来模拟树结构:对于从零开始的索引,元素 N 的子节点分别位于索引 2N + 1 和 2N + 2 处。
本文将分三部分展开:首先简要介绍 heapq 模块的基本用法;其次回顾堆排序算法的核心思想;最后深入分析 heapq 模块的具体实现源码。
heapq 的基本使用
构建堆主要有两种基础方法:heappush() 用于逐个添加元素,heapify() 用于将现有列表转换为堆;而 heappop() 则用于提取堆顶元素。
heappush() 函数用于向现有堆中添加新元素,通常建议从空列表开始逐步构建:
import heapq

data = [97, 38, 27, 50, 76, 65, 49, 13]
heap = []

for n in data:
 heapq.heappush(heap, n)

print('pop:', heapq.heappop(heap)) # pop: 13
print(heap) # [27, 50, 38, 97, 76, 65, 49]
若数据已存在于列表中,则应使用 heapify() 进行原地重排:
import heapq

data = [97, 38, 27, 50, 76, 65, 49, 13]

heapq.heapify(data)

print('pop:', heapq.heappop(data)) # pop: 13
print(data) # [27, 38, 49, 50, 76, 65, 97]
堆排序算法回顾
堆排序的核心思想是:首先将无序序列构建成一个堆,从而获得关键字最小(或最大)的记录;输出堆顶的最小(大)值后,将剩余的 n-1 个元素重新调整为堆,从而得到次小(大)值;重复此过程,最终生成有序序列。
堆排序主要需要解决两个关键问题:
- 如何由一个无序序列构建出一个堆?
- 如何在输出堆顶元素后,调整剩余元素使其重新成为堆?
- 在添加新元素后,如何调整堆结构?
首先探讨第二个问题的解决方案,该方法称为“筛选”。当输出堆顶元素后,将堆中最后一个元素移至堆顶;接着比较根节点与其左右子树根节点的值,并与较小者交换;重复上述操作直至到达叶子节点,从而得到新的堆。这一从堆顶至叶子的调整过程被称为“筛选”。
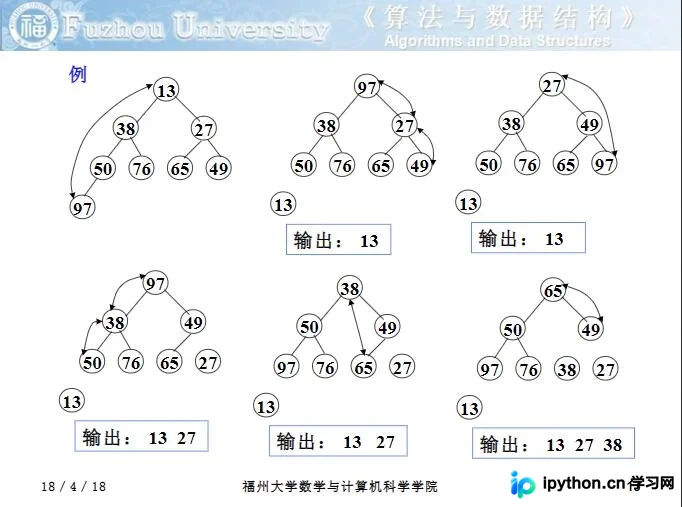
如上图所示,当堆顶元素 13 被输出后,将堆末尾的元素 97 移至堆顶;随后 97 与其子节点 38 和 27 中较小者(27)交换;接着 97 在新位置与其子节点 65 和 49 中较小者(49)交换;直到 97 成为叶子节点,新的堆即构建完成。这一过程也被称为“下沉”。
使位于位置 pos 的元素进行下沉的代码如下:
def heapdown(heap, pos):
 endpos = len(heap)
 while pos < endpos:
 lchild = 2 * pos + 1
 rchild = 2 * pos + 2
 if lchild >= endpos: # 如果pos已经是叶节点,退出循环
  break
 childpos = lchild # 假设要交换的节点是左节点
 if rchild < endpos and heap[childpos] > heap[rchild]:
  childpos = rchild

 if heap[pos] < heap[childpos]: # 如果节点比子节点都小,退出循环
  break
 heap[pos], heap[childpos] = heap[childpos], heap[pos] # 交换
 pos = childpos
接下来探讨第三个问题:如何调整新添加的元素?该方法与“下沉”相反,首先将新元素置于列表末尾,然后将其与父节点比较;若新元素小于父节点,则与父节点交换;重复此过程,直到新元素大于父节点或到达根节点。这一过程使元素从底部不断上升,自下而上恢复堆的顺序,称为“上浮”。
对位置为 pos 的元素进行上浮的代码如下:
def heapup(heap, startpos, pos): # 如果是新增元素,startpos 传入 0
 while pos > startpos:
 parentpos = (pos - 1) // 2
 if heap[pos] < heap[parentpos]:
  heap[pos], heap[parentpos] = heap[parentpos], heap[pos]
  pos = parentpos
 else:
  break
第一个问题:如何由无序序列建立堆?从无序序列的第 n/2 个元素(即对应完全二叉树的最后一个非终端节点)开始,直至第一个元素,依次执行下沉操作:
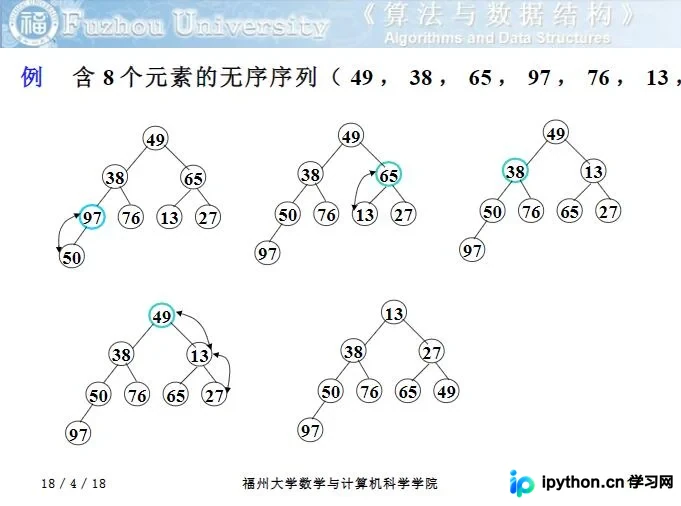
for i in reversed(range(len(data) // 2)):
 heapdown(data, i)
heapq 源码分析
以下是向堆中添加新元素的 heappush() 函数源码:
def heappush(heap, item):
 """Push item onto heap, maintaining the heap invariant."""
 heap.append(item)
 _siftdown(heap, 0, len(heap)-1)
该函数将目标元素置于列表末尾,随后执行上浮操作。尽管函数名看似涉及向下操作,但实际执行的是上浮逻辑。这种命名困惑源于元素索引不断减小,因此命名为 down(下沉);而相反方向的调整则被命名为 up(上浮)。
def _siftdown(heap, startpos, pos):
 newitem = heap[pos]
 # Follow the path to the root, moving parents down until finding a place
 # newitem fits.
 while pos > startpos:
  parentpos = (pos - 1) >> 1
  parent = heap[parentpos]
  if newitem < parent:
   heap[pos] = parent
   pos = parentpos
   continue
  break
 heap[pos] = newitem
该实现同样通过 newitem 不断与父节点进行比较。不同之处在于,这里省略了元素交换步骤,而是计算出新元素最终所在的位置 pos 并直接赋值。这显然是经过优化的代码,减少了频繁交换元素带来的冗余开销。
接下来分析输出堆顶元素的 heappop() 函数:
def heappop(heap):
 """Pop the smallest item off the heap, maintaining the heap invariant."""
 lastelt = heap.pop() # raises appropriate IndexError if heap is empty
 if heap:
  returnitem = heap[0]
  heap[0] = lastelt
  _siftup(heap, 0)
  return returnitem
 return lastelt
该函数通过 heap.pop() 获取列表最后一个元素,将其值赋给堆顶 heap[0] = lastelt,随后执行下沉操作:
def _siftup(heap, pos):
 endpos = len(heap)
 startpos = pos
 newitem = heap[pos]
 # Bubble up the smaller child until hitting a leaf.
 childpos = 2*pos + 1 # 左节点,默认替换左节点
 while childpos < endpos:
  # Set childpos to index of smaller child.
  rightpos = childpos + 1 # 右节点
  if rightpos < endpos and not heap[childpos] < heap[rightpos]:
   childpos = rightpos # 当右节点比较小时,应交换的是右节点
  # Move the smaller child up.
  heap[pos] = heap[childpos]
  pos = childpos
  childpos = 2*pos + 1
 # The leaf at pos is empty now. Put newitem there, and bubble it up
 # to its final resting place (by sifting its parents down).
 heap[pos] = newitem
 _siftdown(heap, startpos, pos)
此段代码将待下沉的元素视为新元素 newitem,将其当前位置 pos 视为空位,由子节点中较小者填补,反复执行此操作,最终在叶子节点留出一个空位,并将 newitem 放入该位置,再让新元素执行上浮操作。
最后分析将无序数列重排为堆的 heapify() 函数:
def heapify(x):
 """Transform list into a heap, in-place, in O(len(x)) time."""
 n = len(x)
 for i in reversed(range(n//2)):
  _siftup(x, i)
这部分逻辑与理论一致,从最后一个非叶节点 (n // 2) 开始,直至根节点,依次执行下沉操作。
总结
结合图示理解堆排序较为直观。这种数据结构常用于优先队列(标准库 Queue 的优先队列即基于堆实现)。heapq 模块中还提供 heapreplace、heappushpop 等函数,其原理与上述类似。
以上为本文全部内容,希望这些内容对您的学习或工作具有参考价值。如有任何疑问,欢迎留言交流,感谢大家对本站的支持。
本站声明
本文内容仅供参考,不代表本站观点。转载或引用请注明出处。如发现内容问题,请通过联系我们页面反馈。















