


Python实现LBP纹理特征提取与图像分类实战

发布时间:2026-10-13 |
3人浏览过
本文介绍基于Python的LBP(局部二值模式)纹理特征提取及SVM分类器实现图像分类的完整流程。针对小规模数据集,通过将512x512图像分割为9块,利用5块训练、4块测试,提取LBP直方图特征。实验结果显示分类正确率达90.6%,并提供了环境配置、代码实现及结果分析。
题目描述与背景
题目描述
本文内容源自数字图像处理课程的大作业项目。
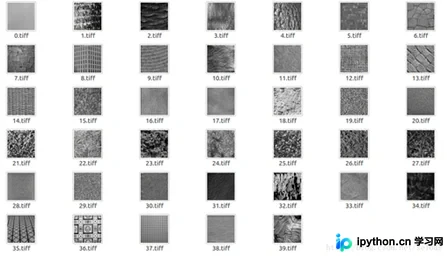
任务要求处理40张不同风格的纹理图片,每张尺寸为512*512。需将每张图片均匀划分为9个相同大小的子区域,选取其中5个子区域作为训练集,剩余4个子区域作为测试集,构建合适的模型以完成图像分类任务。
具体图片示例如下图所示:
鉴于数据集规模较小,直接应用神经网络模型可能并不适宜。因此,本文采用LBP(局部二值模式)方法提取图像纹理信息,并将其转化为直方图作为特征向量,最后使用多分类算法进行分类处理。
运行环境与数据集
运行环境
Python 2.7版本,Jupyter Notebook编辑器,Anaconda发行版。
数据集获取地址
Python代码实现流程
代码实现部分
数据读取与预处理
利用Numpy包的数组操作API对数据进行格式化整理。
def loadPicture():
  train_index = 0;
  test_index = 0;
  train_data = np.zeros( (200,171,171) );
  test_data = np.zeros( (160,171,171) );
  train_label = np.zeros( (200) );
  test_label = np.zeros( (160) );
  for i in np.arange(40):
    image = mpimg.imread('picture/'+str(i)+'.tiff');
    data = np.zeros( (513,513) );
    data[0:image.shape[0],0:image.shape[1]] = image;
    #切割后的图像位于数据的位置
    index = 0;
    #将图片分割成九块
    for row in np.arange(3):
      for col in np.arange(3):
        if index<5:
          train_data[train_index,:,:] = data[171*row:171*(row+1),171*col:171*(col+1)];
          train_label[train_index] = i;
          train_index+=1;
        else:
          test_data[test_index,:,:] = data[171*row:171*(row+1),171*col:171*(col+1)];
          test_label[test_index] = i;
          test_index+=1;
        index+=1;
  return train_data,test_data,train_label,test_label;
特征提取环节
具体采用LBP特征提取算法。
radius = 1;
n_point = radius * 8;

def texture_detect():
  train_hist = np.zeros( (200,256) );
  test_hist = np.zeros( (160,256) );
  for i in np.arange(200):
    #使用LBP方法提取图像的纹理特征.
    lbp=skft.local_binary_pattern(train_data[i],n_point,radius,'default');
    #统计图像的直方图
    max_bins = int(lbp.max() + 1);
    #hist size:256
    train_hist[i], _ = np.histogram(lbp, normed=True, bins=max_bins, range=(0, max_bins));

  for i in np.arange(160):
    lbp = skft.local_binary_pattern(test_data[i],n_point,radius,'default');
    #统计图像的直方图
    max_bins = int(lbp.max() + 1);
    #hist size:256
    test_hist[i], _ = np.histogram(lbp, normed=True, bins=max_bins, range=(0, max_bins));


  return train_hist,test_hist;
分类器训练过程
选用SVM(支持向量机)作为分类模型。
import matplotlib.image as mpimg
import matplotlib.pyplot as plt
import numpy as np
from sklearn.multiclass import OneVsRestClassifier
from sklearn.svm import SVR
from skimage import feature as skft
train_data,test_data,train_label,test_label= loadPicture();
train_hist,test_hist = texture_detect();
svr_rbf = SVR(kernel='rbf', C=1e3, gamma=0.1);
OneVsRestClassifier(svr_rbf,-1).fit(train_hist, train_label).score(test_hist,test_label)
实验结果与总结
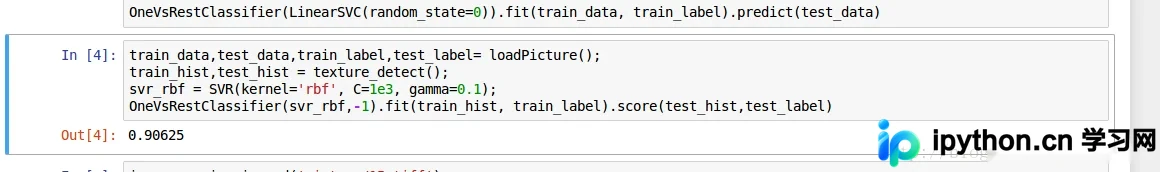
在实验测试集上的分类正确率为90.6%。
这是首次使用Python的Numpy库,对其API尚不熟悉,代码仍有优化空间。此外,Numpy的矩阵操作与Matlab存在差异,但Scikit-learn库在机器学习方面确实提供了便捷的支持。
总结而言,当前分类正确率仍有提升空间,后续可尝试优化分类器参数或探索更高效的特征提取方法。
以上内容为本文全部分享,希望能对读者的学习有所帮助,也欢迎多多支持本站。
本站声明
本文内容仅供参考,不代表本站观点。转载或引用请注明出处。如发现内容问题,请通过联系我们页面反馈。















