


Python列表去重:20种实现方法与性能对比

发布时间:2026-10-12 |
1人浏览过
本文深入探讨Python中列表去重的多种实现方式,涵盖新建列表、原地删除、利用Set和Dict结构以及NumPy库等近20种方法。通过具体代码示例与时间复杂度分析,对比各方案在Python 2.7及更高版本中的执行效率与适用场景,帮助开发者根据实际需求选择最优的去重策略。
说明
在Python语言中,列表(List)作为一种有序的集合数据结构,其特性与其他编程语言中的数组(Array)相似。Python列表能够容纳各种数据类型,且长度支持动态调整,这与JavaScript中的数组或Java中的ArrayList非常接近。在实际开发过程中,去除列表中的重复元素、保持成员的唯一性是一个常见需求。实现这一目标的方法多种多样,例如可以创建一个新的列表来存储非重复项,或者在原列表基础上直接删除重复元素,也可以借助特定的数据结构来达成去重目的。究竟哪种方法更为优越?下文将介绍大约20种可行的实现方案,供读者交流与学习参考。
方式
## 1. 新建列表,如果新列表中不存在,则添加到新列表。
def unique(data):
 new_list = []
 for item in data:
 if item not in new_list:
  new_list.append(item)
 return new_list
# test
data = ['a', 'a', 1, 1, 2, 2, 'b', 'b', 2, 1]
start_time = time.time()
print("new_list + not in data:", unique(data))
print("time:" + str((time.time() - start_time) * 1000) + " ms")
# result
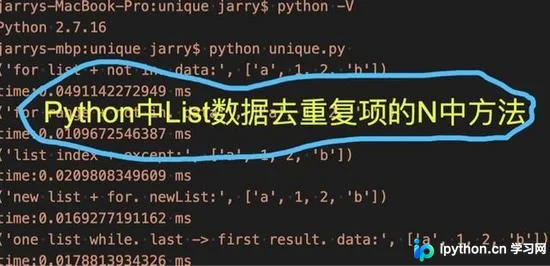
$ python -V
Python 2.7.16
$ python unique.py
('for list + not in. data:', ['a', 1, 2, 'b'])
time:0.0441074371338 ms
## 2. 新建列表。根据下标判断是否存在新列表中,如果新列表中不存在则添加到新列表。
def unique(data):
 new_list = []
 for i in range(len(data)):
 if data[i] not in new_list:
  new_list.append(data[i])
 return new_list
## 2.1 新建列表,使用列表推导来去重。是前一种的简写。
def unique(data):
 new_list = []
 [new_list.append(i) for i in data if not i in new_list]
 return new_list
# test
data = ['a', 'a', 1, 1, 2, 2, 'b', 'b', 2, 1]
start_time = time.time()
print("for range + not in. data:", unique(data))
print("time:" + str((time.time() - start_time) * 1000) + " ms")
## 3. 通过index找不到该项,则追加到新列表中。index找不到会报错,因此放在异常处理里。
def unique(data):
 new_list = []
 for i in range(len(data)):
 item = data[i]
 try:
  if (new_list.index(item) < 0):
  print('new_list:', new_list)
 except ValueError:
  new_list.append(item)
 return new_list
# test
data = ['a', 'a', 1, 1, 2, 2, 'b', 'b', 2, 1]
start_time = time.time()
print("list index + except:", unique(data))
print("time:" + str((time.time() - start_time) * 1000) + " ms")
## 4. 新建列表,两个循环。如果内循环与外循环项相同,且下标相同就添加到新列表,其余忽略
def unique(data):
 new_list = []
 for i in range(len(data)):
 j = 0
 while j <= i:
  if data[i] == data[j]:
  if i == j:
   new_list.append(data[i])
  break
  j += 1
 return new_list
# test
data = ['a', 'a', 1, 1, 2, 2, 'b', 'b', 2, 1]
start_time = time.time()
print("new list + for. new_list:", unique(data))
print("time:" + str((time.time() - start_time) * 1000) + " ms")
## 5. 在原有列表上移除重复项目。自后往前遍历,逐个与前面项比较,如果值相同且下标相同,则移除当前项。
def unique(data):
 l = len(data)
 while (l > 0):
 l -= 1
 i = l
 while i > 0:
  i -= 1
  if data[i] == data[l]:
  del data[l]
  break
 return data
# test
data = ['a', 'a', 1, 1, 2, 2, 'b', 'b', 2, 1]
start_time = time.time()
print("one list while. last -> first result. data:", unique(data))
print("time:" + str((time.time() - start_time) * 1000) + " ms")
## 6. 在原有列表上移除重复项目。自前往后遍历,逐个与后面项比较,如果值相同且下标相同,则移除当前项。
def unique(data):
 l = len(data)
 i = 0
 while i < l:
 j = i + 1
 while j < l:
  if data[i] == data[j]:
  del data[j]
  l -= 1
  i -= 1
  break
  j += 1
 i += 1
 return data
# test
data = ['a', 'a', 1, 1, 2, 2, 'b', 'b', 2, 1]
start_time = time.time()
print("one list while. first -> last result. data:", unique(data))
print("time:" + str((time.time() - start_time) * 1000) + " ms")
## 7. 新建列表。遍历列表,利用index比较出现的位置,如果出现在第一次的位置则追加到新数组。
def unique(data):
 new_list = []
 for i in range(len(data)):
 if i == data.index(data[i]):
  new_list.append(data[i])
 return new_list
# test
data = ['a', 'a', 1, 1, 2, 2, 'b', 'b', 2, 1]
start_time = time.time()
print("for range + index. data:", unique(data))
print("time:" + str((time.time() - start_time) * 1000) + " ms")
## 8. 利用字典属性唯一性来实现去重复。
def unique(data):
 obj = {}
 for item in data:
 obj[item] = item
 return obj.values()
# test
data = ['a', 'a', 1, 1, 2, 2, 'b', 'b', 2, 1]
start_time = time.time()
print("list + dict:", unique(data))
print("time:" + str((time.time() - start_time) * 1000) + " ms")
## 或者直接通过dict.fromkeys来实现
print("dict fromkeys:", dict.fromkeys(data).keys())
## 9. 利用filter函数,即把不符合条件的过滤掉。这里filter不支持下标,因此需要借助外部列表存储不重复项
def uniq(item):
 i = data.index(item)
 if (item not in new_list):
 new_list.append(item)
 return True
 return False
def unique(item):
 if obj.get(item) == None:
 obj[item] = item
 return True
 return False
# test
data = ['a', 'a', 1, 1, 2, 2, 'b', 'b', 2, 1]
start_time = time.time()
new_list = []
print('filter + list + not in: ', filter(uniq, data))
print("time:" + str((time.time() - start_time) * 1000) + " ms")
## 10. 利用字典结合过滤来实现去重复。
def unique(item):
 if obj.get(item) == None:
 obj[item] = item
 return True
 return False
# test
data = ['a', 'a', 1, 1, 2, 2, 'b', 'b', 2, 1]
start_time = time.time()
obj = {}
print("filter + dict + get:", filter(unique, data))
print("time:" + str((time.time() - start_time) * 1000) + " ms")
## 11. 利用map来实现去重复。与map与filter类似,是一个高阶函数。可以针对其中项逐个修改操作。
## 与filter不同map会保留原有项目,并不会删除,因此值可以改为None,然后再过滤掉。
def unique(item):
 if item not in new_list:
 new_list.append(item)
 return item
 return None
# test
data = ['a', 'a', 1, 1, 2, 2, 'b', 'b', 2, 1]
new_list = []
start_time = time.time()
print("list from Map:", filter(lambda item: item != None, map(unique, data)))
print("time:" + str((time.time() - start_time) * 1000) + " ms")
## 12. 利用set数据结构里key的唯一性来去重复
data = ['a', 'a', 1, 1, 2, 2, 'b', 'b', 2, 1]
print("from Set:", list(set(data)))
print("time:" + str((time.time() - start_time) * 1000) + " ms")
## 13. 提前排序,从后向前遍历,将当前项与前一项对比,如果重复则移除当前项
def unique(data):
 data.sort()
 l = len(data)
 while (l > 0):
 l -= 1
 if (data[l] == data[l - 1]):
  data.remove(data[l])
 return data
# test
data = ['a', 'a', 1, 1, 2, 2, 'b', 'b', 2, 1]
start_time = time.time()
print("sort + remove:", unique(data))
print("time:" + str((time.time() - start_time) * 1000) + " ms")
## 14. 提前排序,自前往后遍历,将当前项与后一项对比,如果重复则移除当前项
def unique(data):
 """
 in python 3: TypeError: '<' not supported between instances of 'int' and 'str'
 need to keep the same Type of member in List
 """
 data.sort()
 l = len(data) - 1
 i = 0
 while i < l:
 if (data[i] == data[i + 1]):
  del data[i]
  i -= 1
  l -= 1
 i += 1
 return data
# test
data = ['a', 'a', 1, 1, 2, 2, 'b', 'b', 2, 1]
start_time = time.time()
print("sort+del ASE:", unique(data))
print("time:" + str((time.time() - start_time) * 1000) + " ms")
## 15. 利用reduce函数来去重复。reduce具有累计的作用,判断如果不在累计结果中出现,则追加到结果中。
import functools
def unique(data):
 new_list = []
 def foo(result, item):
 if isinstance(result, list) == False:
  result = [result]
 return result if item in result else result + [item]
 return functools.reduce(foo, data)
# test
data = ['a', 'a', 1, 1, 2, 2, 'b', 'b', 2, 1]
start_time = time.time()
print("functools.reduce:", unique(data))
print("time:" + str((time.time() - start_time) * 1000) + " ms")
## 16. 利用递归调用来去重复。递归自后往前逐个调用,当长度为1时终止。
## 当后一项与前任一项相同说明有重复,则删除当前项。相当于利用自我调用来替换循环
def recursion_unique(data, len):
 if (len <= 1):
 return data
 l = len
 last = l - 1
 is_repeat = False
 while (l > 1):
 l -= 1
 if (data[last] == data[l - 1]):
  is_repeat = True
  break
 if (is_repeat):
 del data[last]
 return recursion_unique(data, len - 1)
# test
data = ['a', 'a', 1, 1, 2, 2, 'b', 'b', 2, 1]
start_time = time.time()
print("recursion_unique:", recursion_unique(data, len(data)))
print("time:" + str((time.time() - start_time) * 1000) + " ms")
## 17. 利用递归调用来去重复的另外一种方式。递归自后往前逐个调用,当长度为1时终止。
## 与上一个递归不同,这里将不重复的项目作为结果拼接起来
def recursion_unique_new(data, len):
 if (len <= 1):
 return data
 l = len
 last = l - 1
 is_repeat = False
 while (l > 1):
 l -= 1
 if (data[last] == data[l - 1]):
  is_repeat = True
  break
 if (is_repeat):
 del data[last:]
 result = []
 else:
 result = [data[last]]
 return recursion_unique_new(data, len - 1) + result
# test
data = ['a', 'a', 1, 1, 2, 2, 'b', 'b', 2, 1]
start_time = time.time()
print("recursion_unique_new:", recursion_unique_new(data, len(data)))
print("time:" + str((time.time() - start_time) * 1000) + " ms")
## 18. 利用numpy lib库. 需提前安装 `pip install numpy`
import numpy as np
def unique(data):
 res = np.array(data)
 return list(np.unique(res))
# test
data = ['a', 'a', 1, 1, 2, 2, 'b', 'b', 2, 1]
start_time = time.time()
print("import numpy as np.unique:", unique(data))
print("time:" + str((time.time() - start_time) * 1000) + " ms")
讨论
从上述示例可以看出,Python相较于其他编程语言具有更高的灵活性。作为与JavaScript并列的最流行脚本语言之一,这种灵活性正是Python广受欢迎的重要原因。
那么,哪种方式最为适合?你通常采用哪种方式来实现去重?是新建数组、非新建操作、借助Dict或Set等数据结构,还是有其他更优的方式?
总结
至此,关于Python列表去重的N种方法介绍完毕。如需了解更多相关Python列表去重内容,请搜索本站历史文章或继续浏览下方的相关文章。希望大家今后能多多支持本站!
本站声明
本文内容仅供参考,不代表本站观点。转载或引用请注明出处。如发现内容问题,请通过联系我们页面反馈。















