


Python多线程与队列技术实战:高效抓取中介网网站排行榜

发布时间:2026-10-16 |
1人浏览过
本文详解如何使用Python结合requests、lxml、threading和queue模块,高效爬取中介网网站排行榜。通过多线程生产者-消费者模型,自动解析总页码并批量抓取域名详情页数据,提供完整的逻辑梳理与代码实现参考。
目标站点分析
本次抓取的目标网站为中介网,该平台提供了包括网站排行榜、互联网网站排行榜及中文网站排行榜在内的多维数据服务。
当前网站展示的样本数据总量为58341条。
采集页面的起始地址为 https://www.zhongjie.com/top/rank_all_1.html。
页面界面布局如下所示:
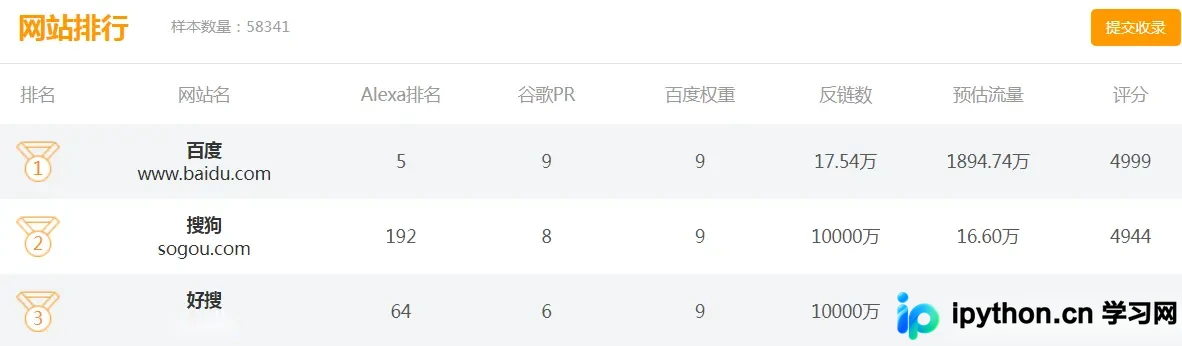
鉴于页面底部存在【尾页】超链接,我们可以直接通过该链接获取累计的总页数,从而确定分页范围。
其余页面的分页逻辑遵循简单的规则:
https://www.zhongjie.com/top/rank_all_1.html
https://www.zhongjie.com/top/rank_all_2.html
基于上述分析,本次Python爬虫的技术方案如下:页面请求采用 requests 库,页面解析使用 lxml,多线程功能依赖 threading 模块,队列管理则继续使用 queue 模块。
编码时间
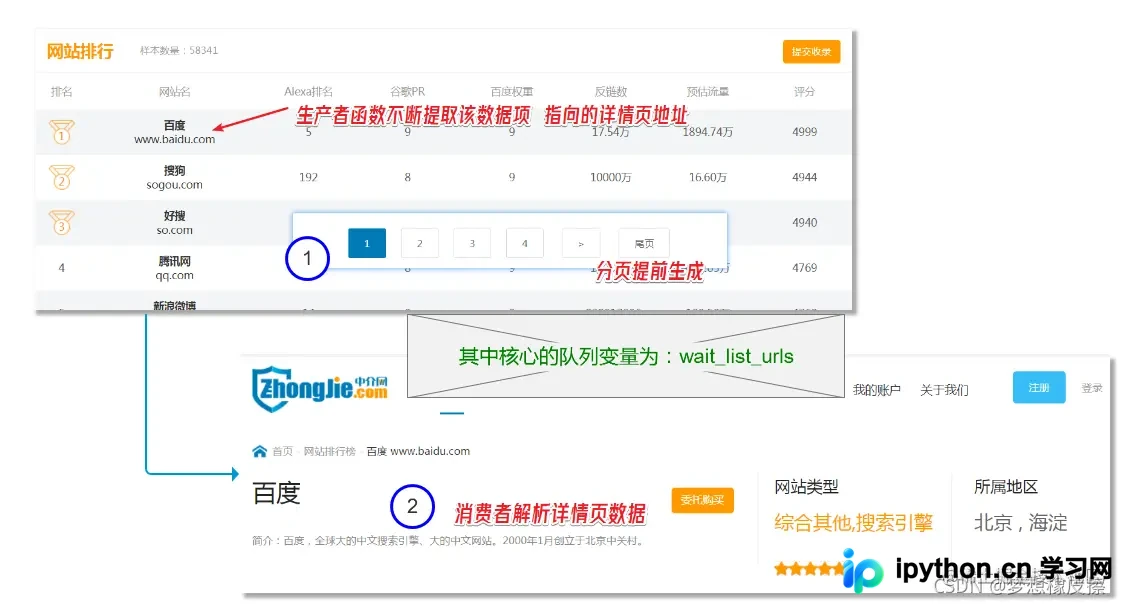
在正式编写代码之前,先通过一张流程图梳理整体逻辑。
本爬虫的编写步骤文字描述如下:
- 首先请求第一页,解析出总页码;
- 接着通过生产者线程不断获取域名详情页地址,并将这些地址添加到队列中;
- 最后由消费者函数从队列中获取详情页地址,并解析出目标数据。
总页码的生成代码非常简单,具体实现如下:
def get_total_page():
	# get_headers() 函数,可参考开源代码分享数据
    res = requests.get(
        'https://www.zhongjie.com/top/rank_all_1.html', headers=get_headers(), timeout=5)
    element = etree.HTML(res.text)
    last_page = element.xpath("//a[@class='weiye']/@href")[0]
    pattern = re.compile('(\d+)')
    page = pattern.search(last_page)
    return int(page.group(1))
总页码生成完毕后,即可进行多线程相关的编码工作。本案例中未编写数据存储部分的代码,这部分功能留给您自行完成。
完整代码如下所示:
from queue import Queue
import time
import threading
import requests
from lxml import etree
import random
import re
def get_headers():
    uas = [
        "Mozilla/5.0 (compatible; Baiduspider/2.0; +http://www.baidu.com/search/spider.html)",
        "Mozilla/5.0 (compatible; Baiduspider-render/2.0; +http://www.baidu.com/search/spider.html)"
    ]
    ua = random.choice(uas)
    headers = {
        "user-agent": ua
    }
    return headers


def get_total_page():
    res = requests.get(
        'https://www.zhongjie.com/top/rank_all_1.html', headers=get_headers(), timeout=5)
    element = etree.HTML(res.text)
    last_page = element.xpath("//a[@class='weiye']/@href")[0]
    pattern = re.compile('(\d+)')
    page = pattern.search(last_page)
    return int(page.group(1))
# 生产者
def producer():
    while True:
        # 取一个分类ID
        url = urls.get()
        urls.task_done()
        if url is None:
            break
        res = requests.get(url=url, headers=get_headers(), timeout=5)
        text = res.text
        element = etree.HTML(text)
        links = element.xpath('//a[@class="copyright_title"]/@href')
        for i in links:
            wait_list_urls.put("https://www.zhongjie.com" + i)
# 消费者
def consumer():
    while True:
        url = wait_list_urls.get()
        wait_list_urls.task_done()
        if url is None:
            break
        res = requests.get(url=url, headers=get_headers(), timeout=5)
        text = res.text
        element = etree.HTML(text)
		# 数据提取,更多数据提取,可自行编写 xpath
        title = element.xpath('//div[@class="info-head-l"]/h1/text()')
        link = element.xpath('//div[@class="info-head-l"]/p[1]/a/text()')
        description = element.xpath('//div[@class="info-head-l"]/p[2]/text()')
        print(title, link, description)
if __name__ == "__main__":
    # 初始化一个队列
    urls = Queue(maxsize=0)
    last_page = get_total_page()
    for p in range(1, last_page + 1):
        urls.put(f"https://www.zhongjie.com/top/rank_all_{p}.html")
    wait_list_urls = Queue(maxsize=0)
    # 开启2个生产者线程
    for p_in in range(1, 3):
        p = threading.Thread(target=producer)
        p.start()
    # 开启2个消费者线程
    for p_in in range(1, 2):
        p = threading.Thread(target=consumer)
        p.start()
到此这篇关于python利用多线程+队列技术爬取中介网互联网网站排行榜的文章就介绍到这了,更多相关python爬取网站排行榜内容请搜索本站以前的文章或继续浏览下面的相关文章希望大家以后多多支持本站!
本站声明
本文内容仅供参考,不代表本站观点。转载或引用请注明出处。如发现内容问题,请通过联系我们页面反馈。















